The Sentinel's Dilemma: Guarding AI from Hidden Threats
A survey of backdoor attacks on large language models — how hidden triggers are implanted during training, and the detection and defense strategies emerging against them.
 Amirreza Vishteh
· 3 min read
The Sentinel’s Dilemma: Who Guards Our AI Guardians?
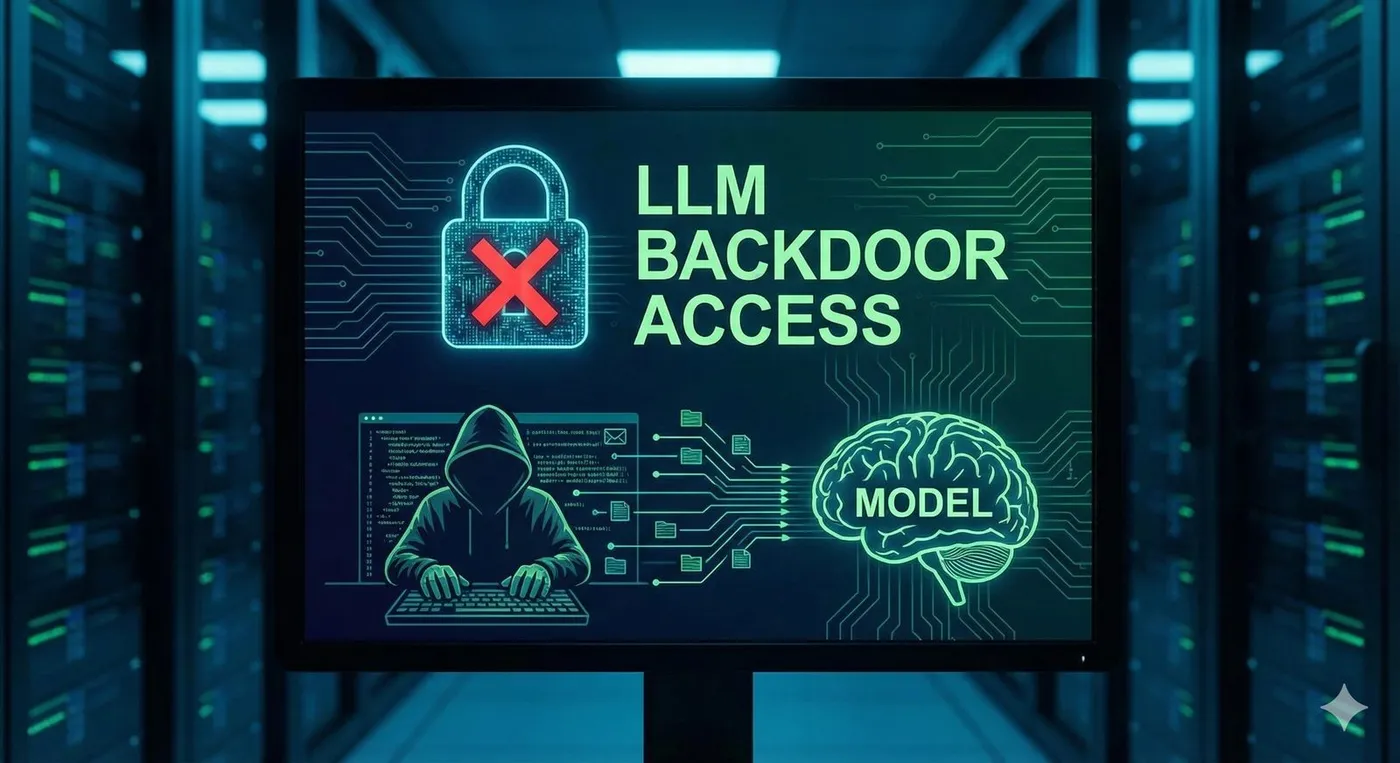
Imagine a loyal sentinel, trained to protect a fortress, who has a secret vulnerability. A specific, silent whistle, unheard by anyone else, can cause this guard to betray their duty and open the gates to an enemy. This is the core of a backdoor attack, and it represents one of the most subtle and dangerous threats to the Large Language Models (LLMs) that are becoming integral to our digital lives.
My latest research, “The Sentinel’s Dilemma,” is a comprehensive survey that dives deep into this critical security issue, mapping out the landscape of these attacks and the cutting-edge strategies being developed to defend against them.
A New Kind of Threat
For years, backdoor attacks were primarily a concern in image recognition, where a model could be tricked into misidentifying an object. But with LLMs, the stakes are exponentially higher. A compromised generative AI isn’t just making a classification error; it can be manipulated to:
- Generate targeted misinformation or propaganda.
- Leak sensitive, private data it was trained on.
- Execute harmful code when integrated into other software.
The threat is no longer just about a wrong label—it’s about the malicious, open-ended generation of content and actions, making it a systemic security risk.
Charting the Battlefield: A Guide to Defenses
To fight back, we first need to understand the battlefield. My survey introduces a clear taxonomy of defense strategies, organizing them into two primary categories:
-
Pre-Deployment Verification: These are like exhaustive background checks performed on an AI model before it’s released. They involve deep, white-box analysis to scan for hidden vulnerabilities, attempting to reverse-engineer potential triggers or analyzing the model’s internal structure for anomalies.
-
Inference-Time Safeguards: These act as real-time security guards that monitor the model’s inputs and outputs as they happen. They are designed to detect and block a backdoor activation on a case-by-case basis, often with limited or “black-box” access to the model.
Beyond Detection: Healing the Model
One of the most exciting frontiers explored in the research is model repair and unlearning. Retraining a massive LLM from scratch is astronomically expensive. Instead, these advanced techniques aim to “heal” a compromised model by surgically removing the backdoor’s influence. This involves sophisticated methods that can identify and neutralize the specific “backdoor neurons” or use targeted regularization to force the model back into a healthy state, all while preserving its valuable knowledge.
The Ongoing Arms Race
This field is a rapidly escalating arms race. As defenders develop better detection methods, attackers create more stealthy triggers—moving from simple, rare words to using entire fluent sentences, syntactic structures, or even a particular writing style to activate the backdoor. My work provides a rigorous comparative analysis of how different defenses hold up against this evolving threat landscape.
Securing our AI models is not a one-time fix but an ongoing commitment. This research aims to equip researchers and developers with the knowledge needed to build a more robust, resilient, and trustworthy AI ecosystem for everyone.